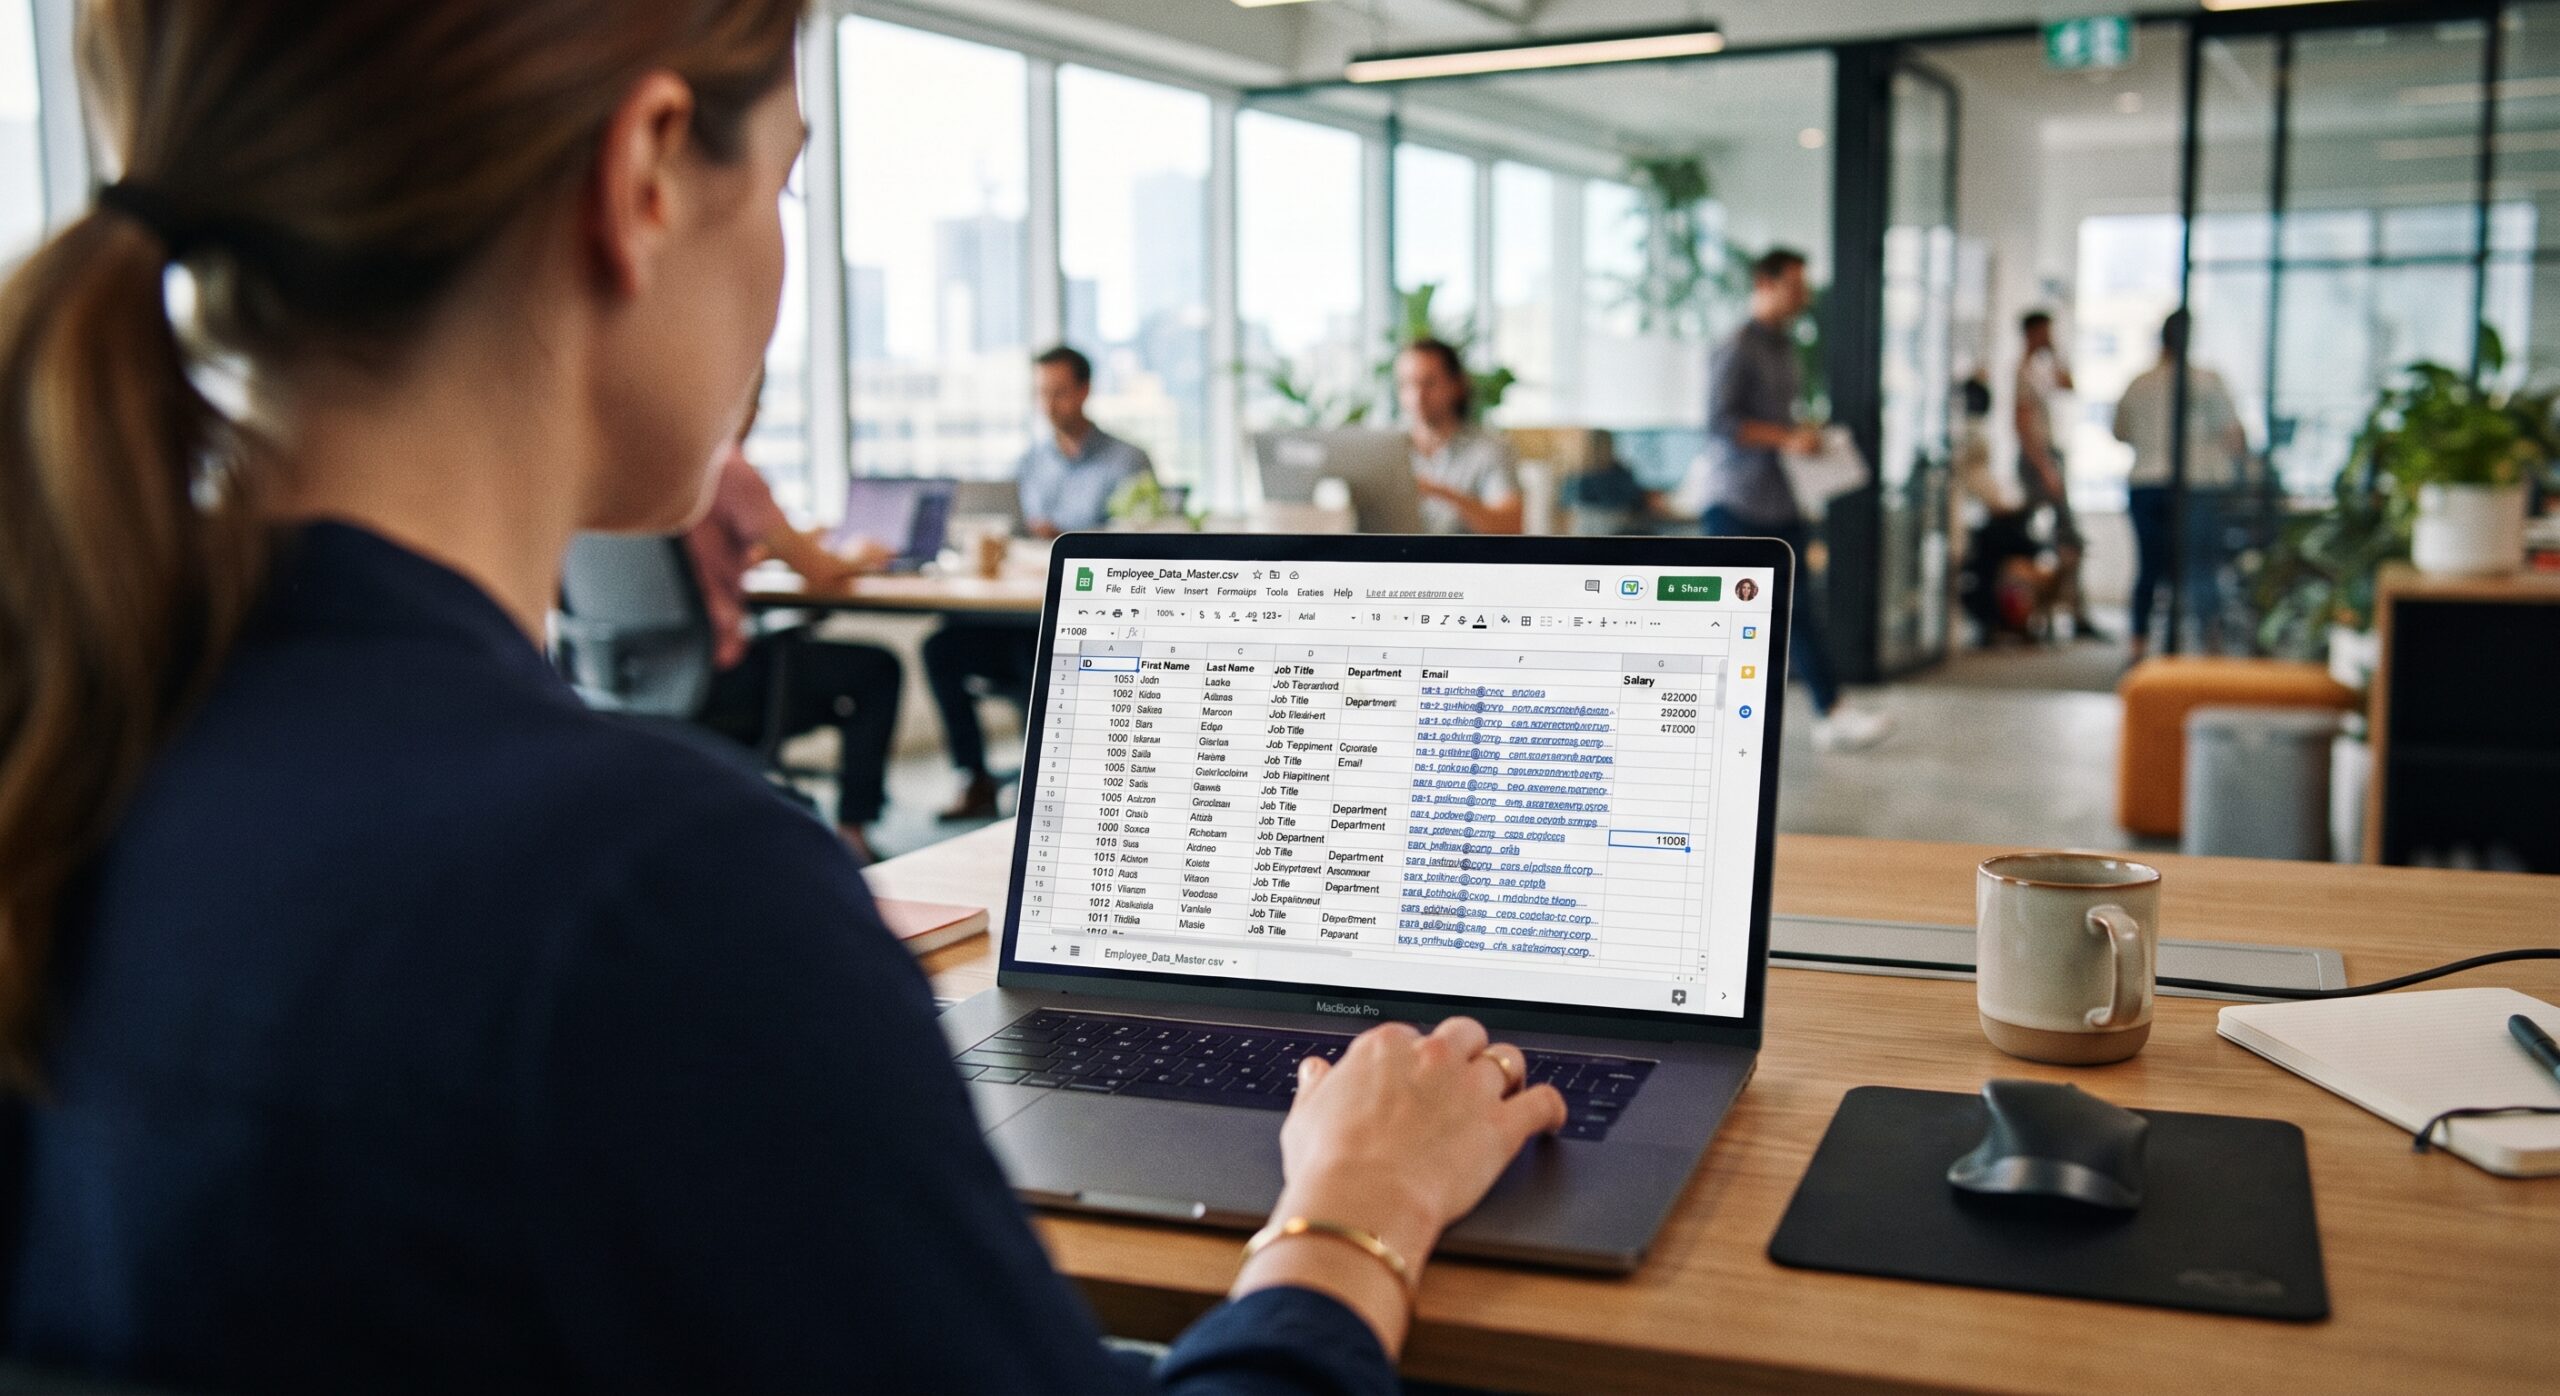
Monday, 9:40 a.m. An export from the CRM sits open in a spreadsheet, the same four thousand rows pulled last week plus whatever changed since. The lifecycle stage column shifted one over during the export, a duplicate list from the webinar platform crept in, and the campaign codes are in the wrong order again. By the time the file is cleaned, checked, and imported into the marketing automation platform, the first hour of the day is gone. Next Monday it happens again.
If this is recognisable, the problem is not that you are slow or disorganised. The spreadsheet is doing a job that should have been done once, by the systems themselves, and it keeps doing it because nobody wired them together.
Why the spreadsheet is still in the middle
Manual sync persists not because people are lazy but because it is the cheapest way to connect two tools nobody bothered to connect. The export button takes ninety seconds to press. Building a proper connection takes a conversation about which system owns which field, and that conversation has not happened, so the spreadsheet stays in the middle and takes the load.
The common sync points in a marketing stack are a short list:
- CRM to marketing automation: contacts, lifecycle stages, and deal status flowing so the right person gets the right sequence.
- Ad platform to reporting: spend and conversion data pulled out of Google, LinkedIn, or Meta and assembled into something readable.
- Event and webinar lists into the CRM: attendees matched to records so follow-up does not start from a blank row.
- Enrichment data back into records: firmographics and firm size updates written into the contact file instead of parked in a separate sheet.
Each of these is a connection someone decided not to own.
What it costs, in hours
The numbers are worse than most teams suspect, and they come from several directions.
Parseur surveyed 500 professionals in operations, finance, admin, IT, and support roles in July 2025. Across those roles, the average person spent more than nine hours per week manually transferring data from emails, PDFs, spreadsheets, and scanned documents into digital systems. By the survey’s estimate, that costs U.S. businesses an average of $28,500 per employee per year. Nearly 60 percent of respondents said they had felt burned out or frustrated by repetitive data tasks, and 46 percent had never used any tool to automate data extraction or entry. That survey is cross-industry, not marketing-specific, but the work it describes is the same work your team does on Monday mornings.
Among analysts, the pattern is even starker. Research by Coleman Parkes for Alteryx, published in February 2025 with 1,400 data, IT, and operations analysts, found that 76 percent still rely on spreadsheets for data preparation tasks. Nearly half, 45 percent, spend over six hours per week on data cleansing and preparation. The study’s finding is that spreadsheet dependency creates inefficiencies and, more importantly, inaccuracies. Again, these are analysts, not marketers, but the dependency is the same dependency.
Within marketing itself, DoubleVerify’s 2025 Global Insights report surveyed 1,970 marketing professionals and found that they spend 10 hours and 12 minutes per week on routine tasks such as bid modifications, budget allocations, and viewability threshold adjustments. That figure covers routine ad-ops work rather than data sync, but it shows where manual repetition lands when nobody owns the repetitive parts of the job. Digital advertising professionals dedicated 26 percent of their work time to repetitive campaign optimizations.
What it costs, in trust
Hours are the visible cost. The quieter one is trust in your own numbers.
The classic study on spreadsheet reliability is Panko’s “Spreadsheet Errors: What We Know. What We Think We Can Do,” published in 2000. Field audits reported in that paper found errors in 24 percent of the 367 spreadsheets examined, roughly one in four. The audits are old, and Panko notes that later audits with better methods found even higher rates. Cell-level error rates in three large audited spreadsheets ran at 1.1 percent, 2.2 percent, and 2.5 percent. A 2 percent cell error rate sounds small until you multiply it by four thousand rows and run a report on the result.
The structural problem is that a manual sync gives one field two sources of truth. The CRM says the contact is a lead. The spreadsheet, three days out of date, says opportunity. The reporting dashboard reads from whichever system was updated last, and nobody checks. A wrong lifecycle stage sends a nurture sequence to a closed-won account. A duplicated contact receives two welcome emails and is counted twice in the pipeline report. The report still renders, still looks authoritative, still gets shared in the Monday meeting. It is just slightly wrong, and the wrongness compounds because nobody believes the numbers enough to question them.
What it costs, in decisions
Data that arrives a week late is a decision made on last week. A campaign adjusted on last month’s conversion data is a campaign aimed at a past audience. A budget reallocation based on a report built from a spreadsheet that missed the Tuesday import is a bet placed blind. None of these decisions are dramatic. They are small corrections stacked week after week, and the stack of small corrections is what the spreadsheet quietly buys you.
The fix is ownership, not another tool
The position from “The tools you can’t count” is still valid: the tool count is a symptom, and the disease is that no one owns how the tools connect. This is the next step in that argument. The CSV export is what people do instead of owning the connection, and the fix is not a better spreadsheet or a new platform sitting on top of the old ones.
The connections are the product. The practical version of that has four parts. Map the sync points, the short list above, and write down what each one currently looks like. Decide which system owns each field, one source of truth per field, so a lifecycle stage exists in exactly one place. Automate the two or three flows that run every week, because those are the ones costing the most hours. And give the whole thing an owner, a person whose job description includes the connections, not just the tool they happen to run.
No rip-and-replace. No software recommendation. A team of four or five with a clear map of who owns what will do more for data quality than any platform purchase.
When I open a client’s stack, the first thing I look for is not the number of tools. It is whether anyone can tell me, which system owns the lifecycle stage and why. Most teams cannot, and that one missing sentence is usually where the real cost is hiding.
The spreadsheet is not the problem. It is the visible symptom of an unowned connection. Owning the flow is a smaller project than replacing anything, and it is the one that actually moves the numbers.
Sources
- Parseur, 2025, https://www.prnewswire.com/news-releases/survey-manual-data-entry-costs-american-companies-more-than-28-000-per-employee-each-year-302516867.html
- Alteryx (Coleman Parkes research), 2025, https://www.alteryx.com/about-us/newsroom/press-release/new-research-reveals-that-ai-brings-productivity-gains-but-reliance-on-spreadsheets-puts-data-quality-at-risk
- Panko, 2000, https://arxiv.org/pdf/0802.3457
- DoubleVerify, 2025, https://ppc.land/doubleverify-study-reveals-marketers-spend-10-hours-weekly-on-manual-tasks/